All work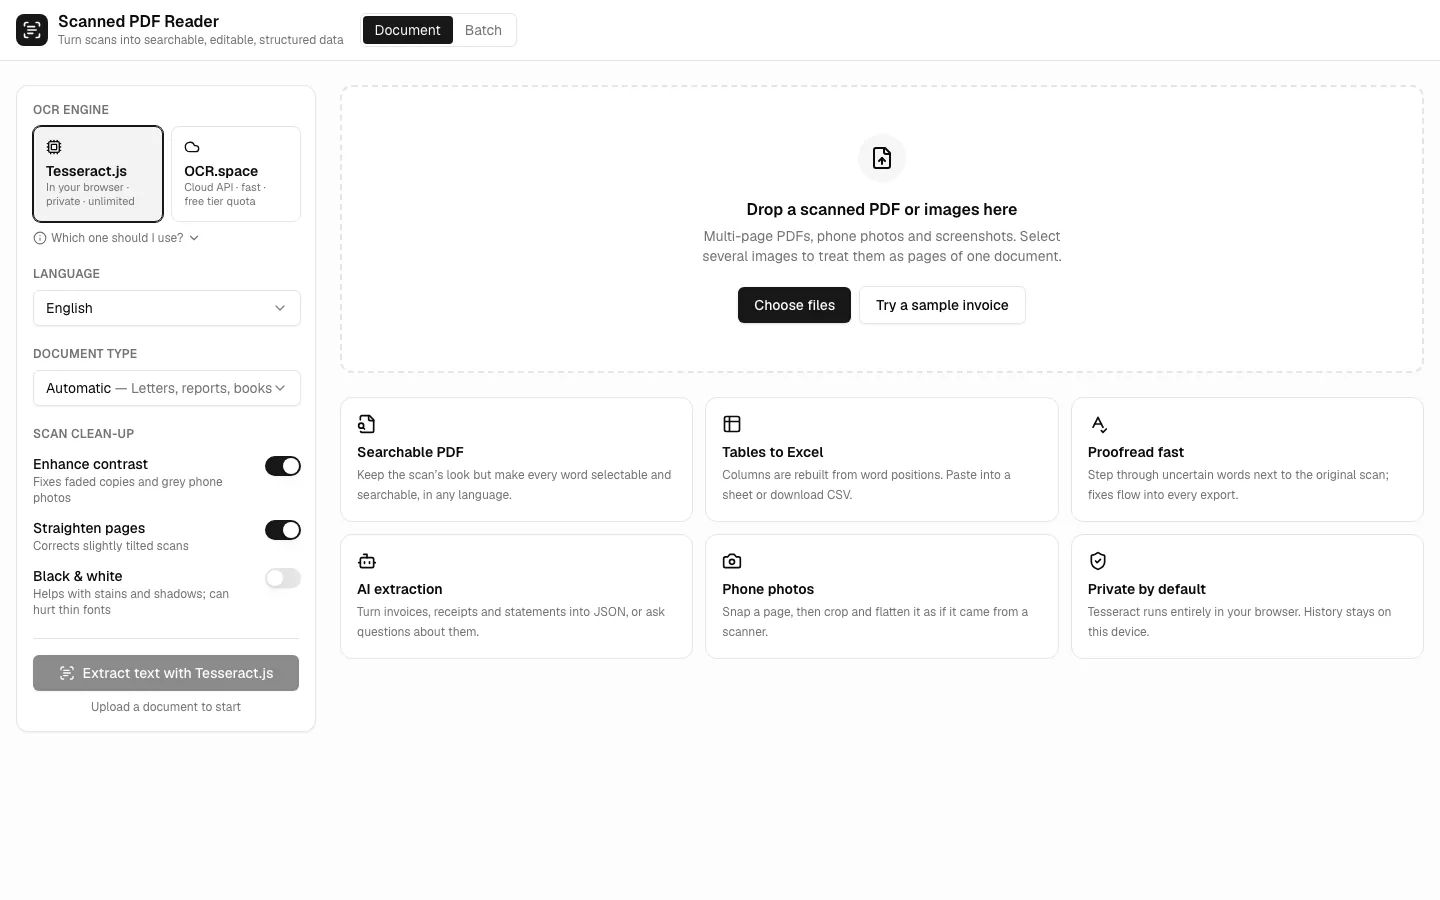
Web App
Scanned PDF Reader
Turn scanned documents into searchable PDFs, Word files, tables and JSON.
pdfreader.illuminext.my
- Client
- Illuminext product
- Category
- Web App
- Year
- 2025
Built with
- Next.js
- Tesseract.js
- OCR.space
- PDF.js
- AI extraction
Drop in a scanned PDF or a phone photo of a document and get back something you can use: a searchable PDF, a Word document, Excel-ready tables, Markdown or structured JSON.
OCR runs privately in the browser with Tesseract.js or in the cloud with OCR.space. Phone photos are edge-detected and flattened as if they came from a scanner.
Highlights
- Multi-page PDFs up to 60 pages
- Automatic page detection and perspective correction
- Export to searchable PDF, DOCX, tables, Markdown or JSON
Next project
RST Energy